RAG, step by step
What is RAG, and why does the answer depend on what the search fetches?
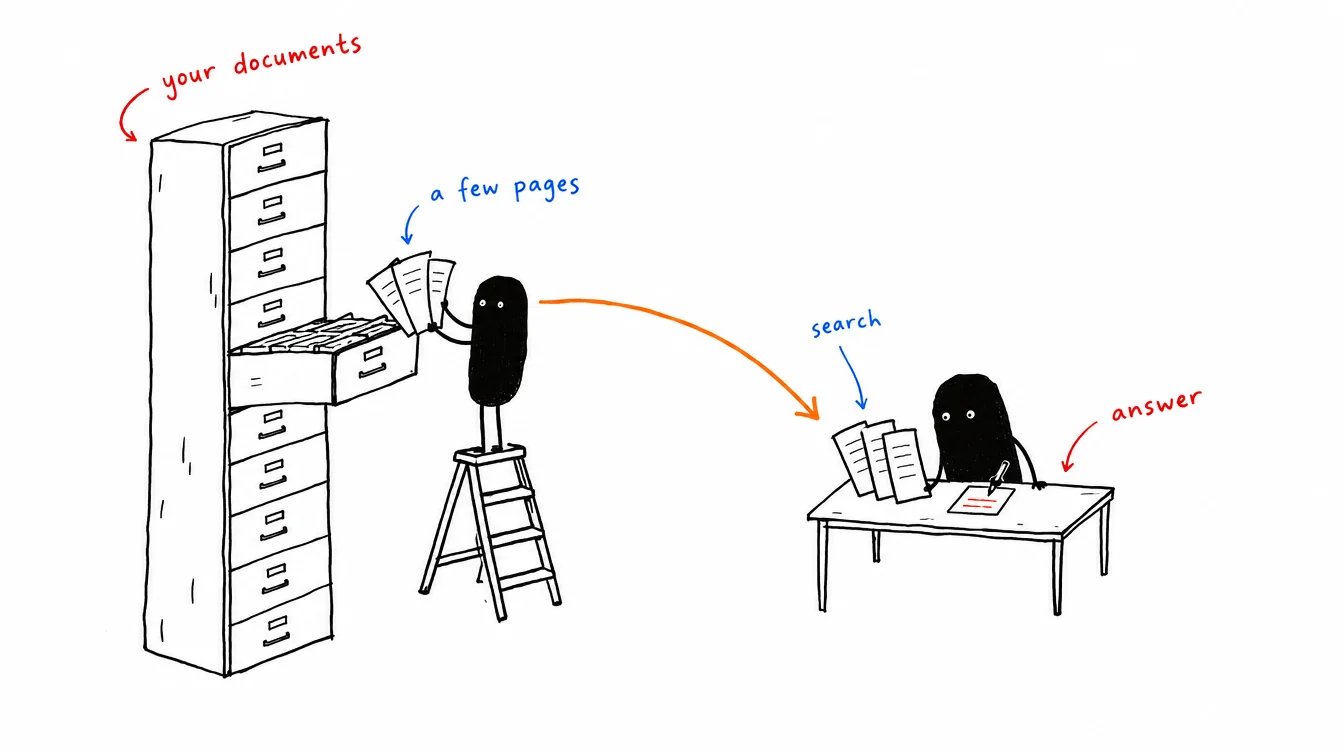
An LLM doesn't know your documents. RAG, retrieval-augmented generation, fixes that in two moves: a search finds a few passages that fit the question, and the model answers from them. Fetch the wrong passages and the model has nothing right to answer from.